Benchmarks
Task completion, cost, and runnable configs. All configs use OPENROUTER_API_KEY.
Terminal-Bench 2.1 · DeepSWE · Run a benchmark
Terminal-Bench 2.1
Claude Opus 4.8 + GLM 5.2
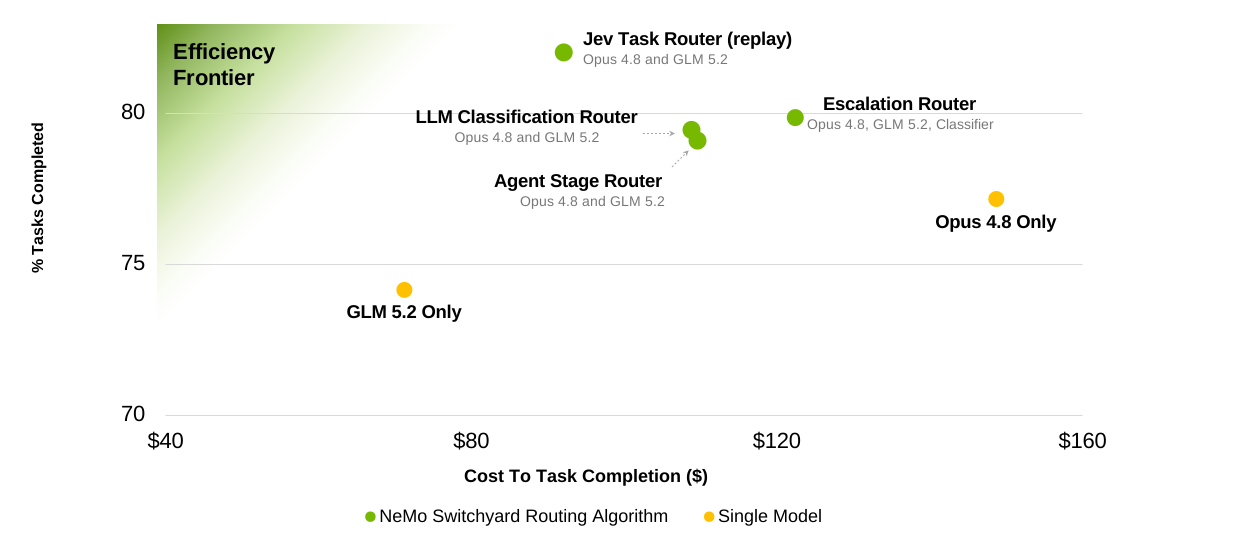
| Strategy | Tasks solved | Cost per run | Config |
|---|---|---|---|
| LLM classifier | 79.40% | $109.04 | — |
| Stage | 79.03% | $109.81 | — |
| Escalation | 79.80% | $122.63 | TOML |
| Jev (replay) | 82.02% | ≈$92.12 | TOML |
| Opus 4.8 only | 77.15% | $148.83 | — |
| GLM 5.2 only | 74.16% | $71.31 | — |
DeepSWE
v1.1 · 113 tasks · Codex CLI · GPT-5.6 Luna + Sol
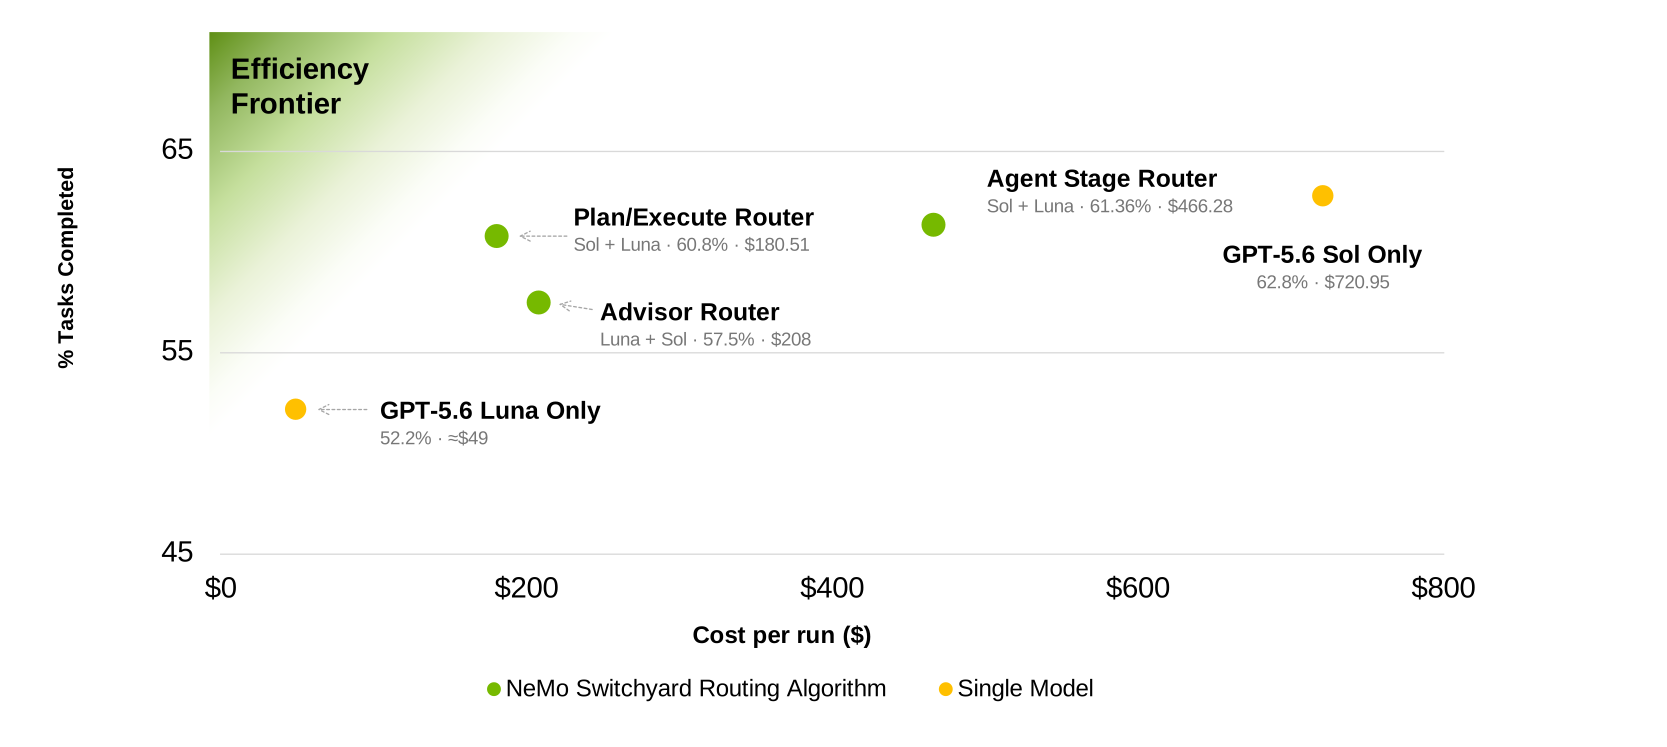
| Strategy | Tasks solved | Cost per run | Config |
|---|---|---|---|
| Plan/Execute | 60.8% | $180.51 | TOML |
| Advisor | 57.5% | $208.00 | TOML |
| Stage | 61.36% | $466.28 | TOML |
| Sol only | 62.8% | $720.95 | — |
| Luna only | 52.2% | ≈$49 | — |
Luna: one run; others: three-run means. Evaluation settings.
Run a benchmark
- Terminal-Bench 2.1: Setup · Run
- DeepSWE: Run with Pier